RoastIQ is most useful when it changes a decision. The mistake teams make is treating a single KPI like the answer.
RoastIQ is the scoring engine inside SaliencyLab, a pre-spend creative intelligence platform: it gives marketers and agency teams a scored, benchmarked read on an ad before media budget is committed, so the launch call improves before the spend happens.
The right order is simple: read the decision cue, read the KPI pattern, read the benchmark context, then read the evidence. That sequence keeps the conversation grounded in the creative instead of drifting into score theatre.
Start with the decision cue
Every report is answering a slightly different question. Is the asset strong enough to scale? Is the opening losing attention? Is the brand being credited? Is the proposition clear enough to support action?
If the team does not agree on the decision first, the report will feel more objective than it really is.
The live structure is easiest to see in the example report, but the rule is the same on every run: decide what the report is supposed to settle before you read the numbers.
What each KPI is doing
The five KPIs are Beat the Skip, Get Noticed, Brand Impact, Sell Proposition, and Build Brand. Each answers a different question about the creative, from whether the opening survives a fast scroll to whether the brand gets credited for the work, and they are weighted 25%, 20%, 20%, 20%, and 15% in the composite. For the full definition of each KPI, the score bands, and how to read the benchmark labels, use the guide to interpreting RoastIQ KPI scores. This post stays focused on reading order, the meeting itself, and the mistakes that derail both.
Read the pattern, not one row
A single strong KPI can hide a structural problem. A single weak KPI can be manageable if the rest of the report supports the launch call.
Common patterns usually look like this:
- strong opening, weak brand credit
- strong brand, weak attention
- clear proposition, weak memorability
- mixed scores with a strong benchmark read
The job is not to crown the best-looking row. The job is to see whether the creative is internally coherent.
The verdict already encodes some of this for you. Scale requires a composite of 70 or above and no KPI below 55, so a creative with one weak row lands in Sharpen even when the average looks strong. Rebuild triggers on a composite below 55, or on two or more KPIs below 45.
Use benchmark context as a calibration tool
Benchmark context is where the report becomes practical. The same raw score can mean different things depending on the format and the platform. A score that is acceptable in one environment may still be too soft in another.
Two things to check before you lean on a percentile. First, the sample size behind the slice, which the report shows rather than hides. Second, whether the platform is one where scores carry held-out validation; more on that below. If someone challenges the bar, the benchmark interpretation guide for creative teams covers how to read norm context before the meeting turns into a guesswork argument.
Benchmarks are also where comparison earns its place. If two cuts are both viable, the report should help the team choose the one that deserves budget, not just the one that feels safe in the room.
What the report can and cannot tell you
RoastIQ’s five KPIs are diagnostic model outputs. The separately reported platform-native attribute model has its own outcome-validation record; its correlations must not be attributed to the five-KPI composite, attention heatmaps or BuyerLens. See the dated methods and validation scope. None of these outputs establishes sales, ROAS or a measured human response to your ad.
A useful habit for the meeting: treat the scores and sample sizes as facts about the model's output, treat the report's suggested next moves as recommendations, and treat any explanation of why an audience might resist as a hypothesis until it is tested.
Avoid the four common mistakes
- Do not average the KPIs into a homemade score. The composite is already weighted
- Do not let the strongest score overrule the weakest one
- Do not treat benchmark context as the strategy
- Do not use the report to avoid a decision
If the discussion sounds like score theatre, the team has probably stopped reading the creative and started negotiating comfort.
The meeting version
If you need a 60-second readout, use this order:
- What decision are we making?
- Which KPI is strongest?
- Which KPI is weakest?
- Does benchmark context change the urgency?
- Do we edit, compare, or pressure-test?
That is usually enough to turn the report into a decision instead of a debate. And when the readout surfaces an audience question the scores cannot settle, that is the moment to pressure-test it with BuyerLens synthetic buyer interviews, which open directly from the RoastIQ result, before committing to human research.
What to read next
- How to test ad creative before launch
- Benchmark interpretation guide for creative teams
- When to use synthetic buyers after a RoastIQ report
A report you can inspect while reading
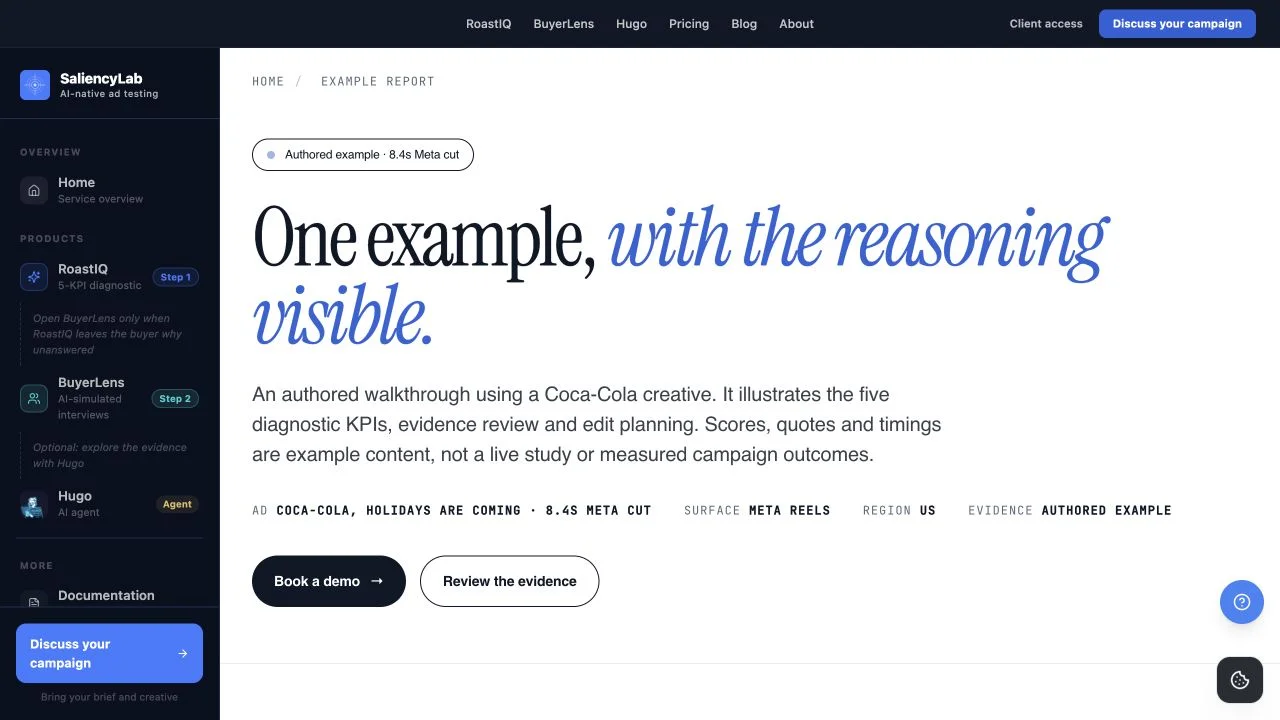
Use these three annotations with the open example: 1 — identity: check the exact cut, platform and region. 2 — decision: read what to preserve and change. 3 — evidence: open the source moments before accepting the explanation. The public page is authored example content, not a completed client analysis.
Know who reviewed the recommendation
“Analysis ready” means the generated output is available. “In review” means review has not finished. “Reviewed” should refer to a recorded review of that report version. Do not imply human approval from a model verdict or from a screenshot alone. If the reviewer or version is unavailable, ask for that context before presenting the advice as approved.
Make the readout usable
| Keep | Change | Back or hold |
|---|---|---|
| Name a specific strength in the asset | Specify the scene, issue and proposed edit | Name the selected creative or the evidence still needed |
Finish with an owner and the next decision. A revision brief makes the edit reviewable, and a six-slide presentation helps a client see why you recommend it.