RoastIQBuyerLensHugoPricingBlogAbout
Client accessDiscuss your campaign
Founder-ledBuilt by someone who used to spend €100k per study

About SaliencyLab

I led creative testing
at L'Oréal.
So I automated it.

SaliencyLab is the pre-spend creative intelligence platform built by an insights operator who worked inside the gap it now addresses, running Kantar studies in 11+ markets, watching small brands guess because the testing budget never reached them. Now it does.

Oussama Nakhil, Founder of SaliencyLab
Founder & CEO · SaliencyLab

The journey

From measuring ads to predicting them.

Oussama Nakhil founded SaliencyLab after working in market research at NielsenIQ (January 2022–June 2024) and as Global Consumer and Market Insights Manager at L’Oréal (September 2024–November 2025). His work included media-testing methodology across 500+ campaigns for six global brands. He began building SaliencyLab part-time in August 2025 and full-time in March 2026.

2022–2024
NielsenIQ · Casablanca

Agency-side. Insights for the giants.

Managed a $3M+ FMCG client portfolio: Coca-Cola, Unilever, PepsiCo, L'Oréal. Delivered monthly insight reports across 10+ categories. Saw exactly which questions brands paid the most to answer.

$3M+ portfolio · 10+ categories
2024–2025
L'Oréal · Paris HQ

Client-side. Running Kantar across markets.

Global Consumer and Market Insights Manager. Led media testing methodology across 500+ campaigns for 6 global brands. Worked on measurement approaches, statistical frameworks and interpretation for creative decisions.

500+ campaigns · 11+ markets
2025
SaliencyLab · Paris

Building. The tool that should have existed.

Same five things that always determined whether an ad would work: does it survive the skip, does the message land, does the brand register, does it persuade, does it build memory. Mapped to peer-reviewed science. Run in minutes.

Images typically take 60–90 seconds. Videos typically take 3–4 minutes, with a longer tail up to 9 minutes.
“

A creative review should end with a clear decision: what to keep, what to change and which ad to back. AI helps us inspect the creative; human review puts those signals into the context of your campaign.

Oussama
Founder · SaliencyLab

The gap we closed

Different evidence. A clearer decision.

AI diagnostics and synthetic interviews support creative decisions. They do not replace research with real consumers.

The old world

Recruit. Survey. Wait. Compile.

  • Recruitment and fieldwork costs
  • Fieldwork and reporting schedules
  • Useful for validation with real participants
  • Scope and cost depend on the study
  • Plan research around the decision

The new world

Upload. Score. Decide. Iterate.

  • Five KPI scores in minutes
  • Used between every edit round, not once before launch
  • Same five constructs that mattered for the giants
  • Now reaches DTC brands and agencies the same week

What we believe

Five rules we don't break.

The principles that decide what we ship and what we refuse to.

Truth before polish

No invented metrics. No overclaims. We keep diagnostic scores, named-model validation, cohort coverage and run stability distinct.

Science, not vibes

Every KPI maps to peer-reviewed work: attention science, cognitive load, brand salience, behavioral psychology. 24 cited papers and counting.

Speed is a feature

Feedback should arrive early enough to inform the next edit. Review scope and timing are agreed with your team.

Built for everyone, not just giants

The DTC founder, the agency creative, the in-house team: same five KPIs, same benchmark frame, same verdict logic. Pricing reflects that.

Recent traction · April 2026

GITEX Africa picked us. So did Morocco.

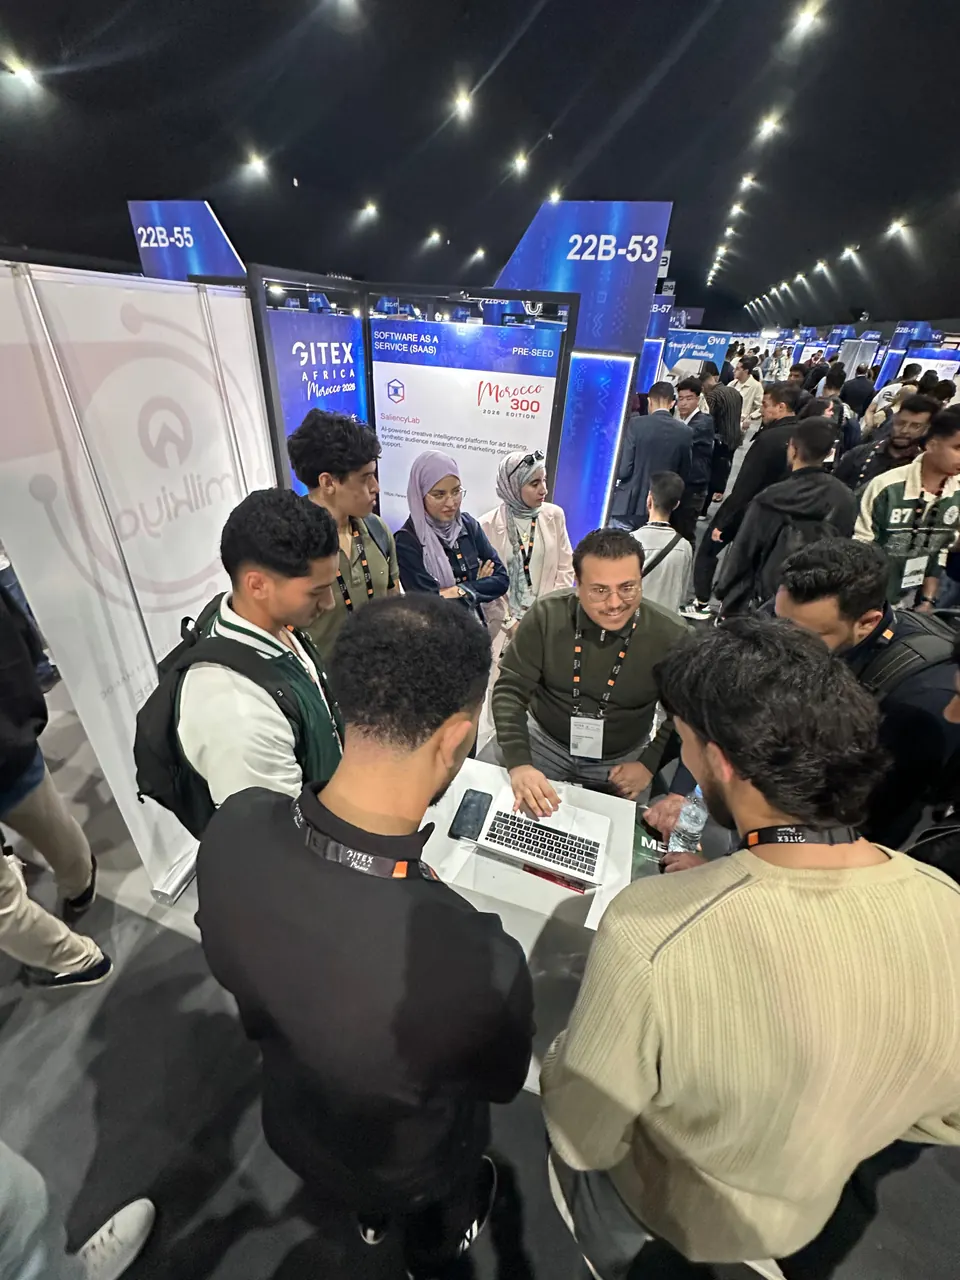
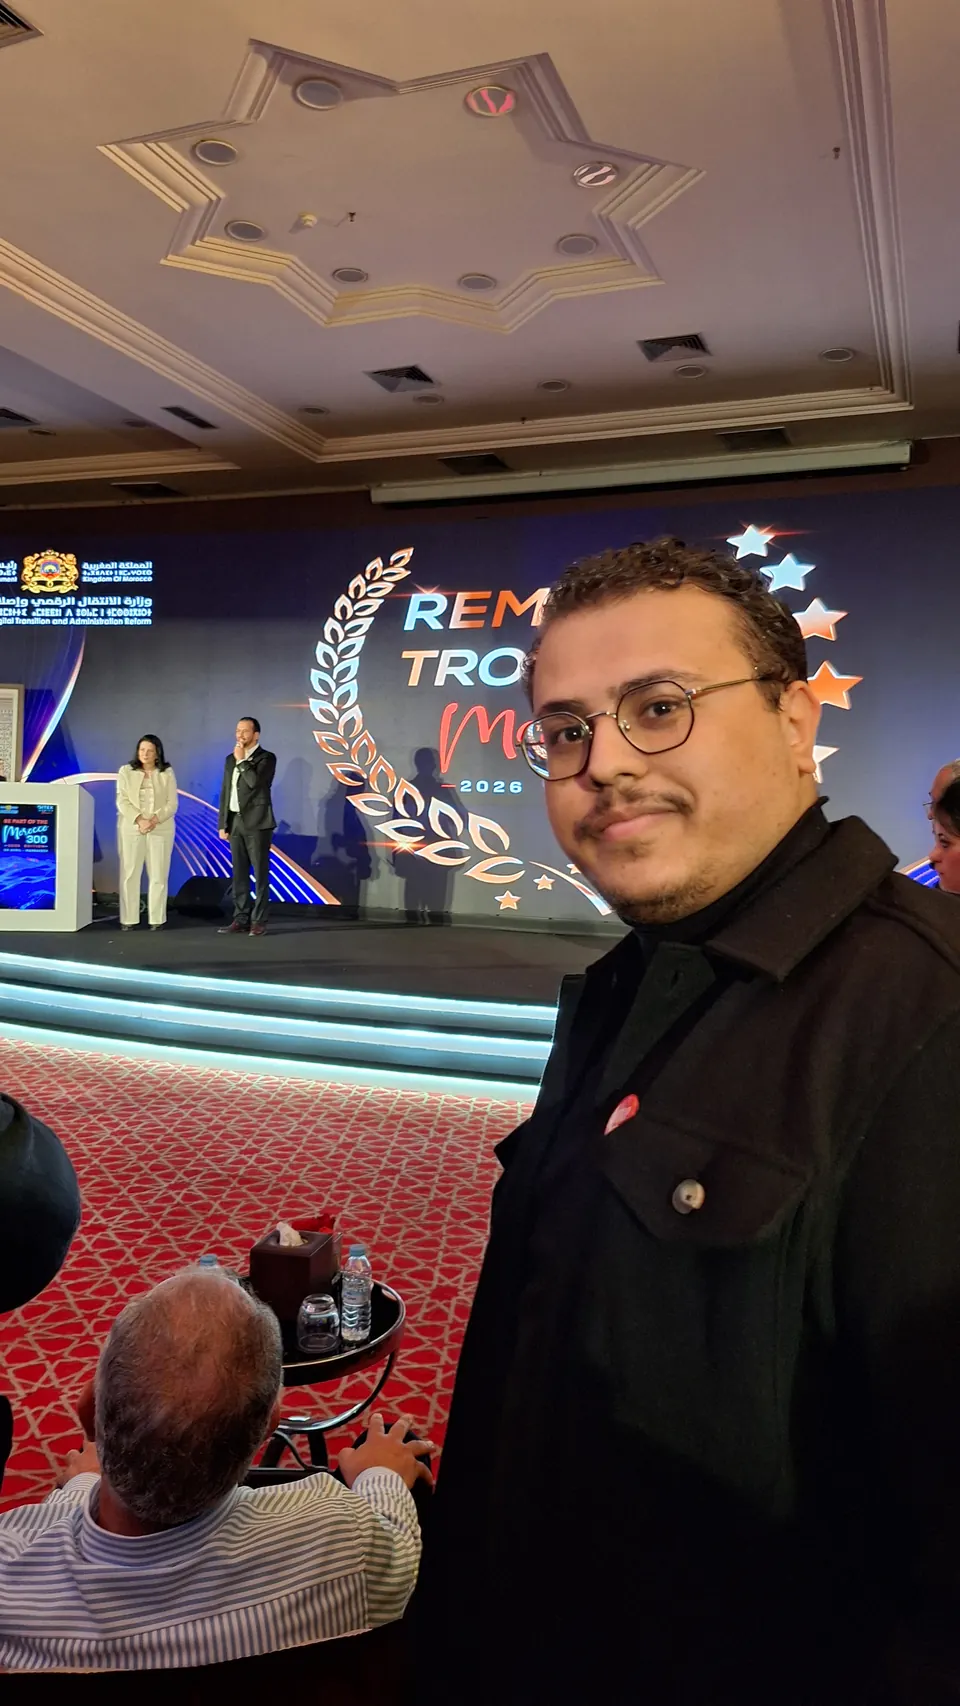
Selected among 300 startups from across the continent. Demoed RoastIQ to AI engineers, agency owners, and global brand teams on the floor. Came back with conversations that turned into our roadmap.

Oussama at the SaliencyLab stand at GITEX Africa 2026

At the SaliencyLab stand

Three days. Live demos. Real conversations with founders and global brand teams.

Selection ceremony at Savoy Le Grand Hotel Marrakech

Selection · Savoy Marrakech

One of 300 startups picked across Africa.

Demoing RoastIQ to AI engineers and agency owners

Live demo on the floor

RoastIQ scoring real ads in minutes.

DigiTalk podcast appearance

DigiTalk · Morocco's biggest digital media

Talking creative intelligence on Morocco's largest digital podcast, full episode in the pipeline.

300
Startups selected from across Africa
29.4K
Views on a single Moroccan-influencer reel
3
Days demoing live to founders & global teams
11+
Markets the founder ran Kantar in before this

What we built

Three products. One decision ladder.

RoastIQ scores the creative. BuyerLens explains the resistance. Hugo orchestrates both, through one conversation.

Step 1 · Diagnostic

RoastIQ

Pre-spend creative scoring

Upload an ad. Get five KPI scores, a verdict (Scale · Sharpen · Rebuild), benchmark position, and the evidence behind it, in minutes.

Open RoastIQ
Step 2 · Resistance

BuyerLens

Synthetic buyer interviews

Opens from a saved RoastIQ result. Run structured interviews across buyer personas, and surface the specific tension before the next cut.

Open BuyerLens
Agent · Orchestrator

Hugo

Autonomous AI creative strategist

One conversation. Hugo runs RoastIQ, explores synthetic buyer interviews, queries benchmarks, and shows the reasoning trace, so the recommendation arrives with its receipts.

Meet Hugo
+0.33
Held-out OOS Spearman ρ, 5-fold CV, TikTok CTR (n=691)
+0.40
Held-out OOS Spearman ρ, 5-fold CV, YouTube view counts (n=397)
6.5×
Pool-wide quintile lift, top vs bottom by predicted score

The science backbone

Evidence for the platform-native attribute model.

These figures describe the platform-native attribute model, a separate model from RoastIQ’s five KPI scores. Held-out results use TikTok CTR and YouTube view-count outcomes, never against in-market business outcomes (sales, ROAS, attributed conversion). Meta scores are directional defaults — outcome data is sparse for brand ads in the current cohort and there is no held-out validation for that platform. Cohort coverage and repeat-run stability must be assessed separately.

Co-authored methodology paper in pipeline with Nissrine Khadir (Mohammed V University Rabat, management sciences). Open-source benchmark dataset planned (CC-BY-NC). 24 peer-reviewed papers cited across the five KPIs.

The named research model is evaluated against platform outcomes; these estimates do not validate every product output. We do not claim to predict in-market sales, ROAS, or brand recall. Heatmaps predict visual attention, not measured eye tracking. Synthetic buyer interviews are scenario simulation, not real consumer panels.

Directories

Dang.ai — AI tools directory

Directory membership is not an independent product evaluation.

Test before you spend

The testing budget you didn't have just arrived.

Bring one ad you are deciding on. We score it live on a 30-minute call, walk through the verdict together, and you leave with the first move into the next round.

Oussama Nakhil