The opening, on the record.
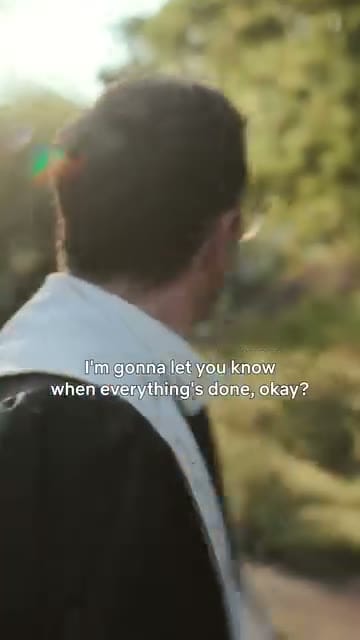
A Netflix Meta spot in the emotional-story register. Watch the first three seconds and read the Netflix grammar, color grade, sound design, without seeing the mark.
Directional creative evidence.
The archived runner returned SHARPEN. This is a historical rule label, not a current decision recommendation. No matched-cohort sample or repeated-run estimate is attached to this example.
Meta has no held-out validation. A platform match alone also does not establish coverage for a market, category or format. Keep these examples directional unless the specific cohort evidence supports a stronger statement.
Where the score comes from.
Archived raw KPI outputs below. Labels describe diagnostic ranges only; they are not measured retention, recall, persuasion or emotional intensity.
// KPI breakdown, Netflix Meta US
 0.5s
 2.0s
 4.0s
 MID
 75%
What the pipeline tagged.
Read the model output.
The archived runner tagged the hook as Emotional-Story, opening motion as Dynamic and value proposition as Emotion-Led. Check these labels against the full creative. Review whether the entertainment story can be attributed to Netflix.
An edit to test.
 END
Test a clearer service cue at a natural story moment. Keep the original, record the change and agree the outcome measure before testing. There is no measured score uplift or campaign result for this proposed revision.
Coverage limits.
This archive identifies the platform and country, but does not attach a matched-cohort sample, a percentile calculation or a repeat-run stability estimate. We therefore do not rank this ad in a category quintile. Validation of the separate platform-native attribute model does not validate these five KPI outputs.
Record the human choice.
Use the example to frame a review question. A human reviewer should record the brief, chosen revision, proposed test and actual result. No client acceptance or in-market outcome is claimed for this case. See the methodology and the brand-cue review guide.